Radical Technologies
Combo Program
★★★★★
(2,088 ratings)  50,000+ Student

DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO Training in Pune

The Data Engineering with Databricks, PySpark & Generative AI Combo course is designed for learners who want to build practical skills in modern data engineering and AI-powered data workflows. The training covers Databricks, PySpark, data processing, ETL pipelines, data lakes, data transformation, and Generative AI applications through hands-on exercises and real-world projects. Learners gain experience working with large datasets and using AI tools to improve data workflows and productivity. This course is ideal for aspiring data engineers, software developers, data analysts, cloud professionals, freshers, and IT professionals looking to build skills in modern data engineering and Generative AI.

RT
Radical Technologies
50,000+ English 38 Modules · 1 Section
Online / Classroom

DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

Sections Included 1 Section (DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO)
Batch Type Weekdays / Weekends
Mode of Training Classroom / Online / Corporate
Locations Pune, Bangalore, Kochi
Language English
Certification Globally Recognized

Tools you'll master

Azure Databricks SQL PySpark Python LangChain GitHub Linux Data Warehousing Big Data

Next batch: Contact us ·

Call Now

100% placement assistance

Enquire Now

Get course fees, batch dates & a callback

We never share your details.

What you'll learn

Program Overview
Who Should Join?

Programme Overview

38 modules across DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO — a single, progressive learning arc from foundational concepts to real-world projects.

1
Programme Sections
38
Total Modules
388
Total Topics
4.8
Average Rating
50K+
Students Trained
01

DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

Master the core concepts and hands-on skills of DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO — from fundamentals to real-world application.

Azure Databricks SQL

Who is this programme for?

Whether you're starting from scratch, know some SQL, or are already writing code — this programme takes you from database fundamentals through Python programming to real-world data analysis.

Students & Freshers

Build a strong foundation in DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO and gain practical, job-ready experience from day one.

Working Professionals

Upskill and combine complementary skills from multiple courses in one structured programme.

Career Switchers

Move into a new technical role with a single, structured path covering everything you need.

IT Professionals

Deepen your expertise and broaden your skill set with hands-on, practical training.

Course Curriculum

1 section  •  38 modules  •  388 topics

Become a Modern Data Engineer by mastering Python, SQL, Apache Spark, PySpark, Databricks, Delta Lake, Azure Data Factory, Apache Kafka, Data Warehousing, ETL/ELT, Cloud Data Engineering, Data Lakes, Generative AI, LLMs, AI Agents, RAG, Vector Databases, MLOps, and Production-Ready Data Pipelines.
This program is designed to prepare candidates for Data Engineering, Big Data Engineering, Analytics Engineering, AI Data Engineering, and Gen AI Data Engineer roles.
• Fresh Graduates
• Software Engineers
• Python Developers
• SQL Developers
• ETL Developers
• BI Developers
• Data Analysts
• Data Scientists
• Cloud Engineers
• DevOps Engineers
• Database Administrators
• AI/ML Enthusiasts
• Working Professionals looking to transition into Data Engineering
• No prior Data Engineering experience required
• Basic computer knowledge
• Logical thinking
• Programming background is helpful but not mandatory
• ✅Python Programming
• ✅Advanced SQL
• ✅Linux Fundamentals
• ✅Data Engineering Fundamentals
• ✅Apache Spark
• ✅PySpark
• ✅Databricks Lakehouse Platform
• ✅Delta Lake
• ✅Azure Data Factory
• ✅Apache Kafka
• ✅Azure Data Lake Storage (ADLS)
• ✅Data Warehousing
• ✅ETL & ELT Pipelines
• ✅Data Modeling
• ✅Git & GitHub
• ✅Azure DevOps / CI-CD
• ✅Docker Fundamentals
• ✅Generative AI
• ✅Large Language Models (LLMs)
• ✅Retrieval-Augmented Generation (RAG)
• ✅LangChain
• ✅LangGraph (Overview)
• ✅AI Agents
• ✅Vector Databases
• ✅Prompt Engineering
• ✅Production Projects
• What is Data Engineering?
• Data Engineer Roles &  Responsibilities
• Data Pipeline Architecture
• Batch vs Streaming
• Data Lakes
• Data Warehouses
• Lakehouse Architecture
• Medallion Architecture
• Enterprise Data Platforms  Data Warehouses
• Lakehouse Architecture
• Medallion Architecture
• Enterprise Data Platforms
• Python Basics
• OOP Concepts
• File Handling
• Exception Handling
• Functions
• Modules
• Pandas
• NumPy
• API Calls
• JSON Processing
• Logging
• Virtual Environments
• SELECT
• JOIN
• GROUP BY
• Window Functions
• CTE (Common Table Expressions)
• Stored Procedures
• Indexing
• Performance Tuning
• Query Optimization
• Advanced SQL Interview Questions
• Linux Commands
• Shell Scripting
• File Management
• Permissions
• Cron Jobs
• Process Management
• Spark Architecture
• Spark Cluster
• Spark SQL
• RDD
• DataFrames
• Transformations
• Actions
• Caching
• Partitioning
• Optimization
• DataFrame API
• Spark SQL
• Data Cleaning
• Data Transformation
• Aggregations
• Window Functions
• UDFs
• Performance Optimization
• Partitioning
• Broadcast Joins
• Databricks Workspace
• Clusters
• Notebooks
• Jobs
• Workflows
• Unity Catalog
• Databricks SQL
• Secrets
• Widgets
• Repos
• Asset Bundles (Overview)
• ACID Transactions
• Delta Tables
• Time Travel
• Schema Evolution
• Merge Operations
• Upserts
• Change Data Feed (CDF)
• Delta Optimization
• Vacuum
• Z-Ordering
• Linked Services
• Pipelines
• Data Flows
• Integration Runtime
• Triggers
• Parameterization
• Scheduling
• Monitoring
• Storage Accounts
• Containers
• File Management
• Security
• Data Organization
• Kafka Architecture
• Producers
• Consumers
• Topics
• Partitions
• Streaming Pipelines
• Real-Time Processing
• Star Schema
• Snowflake Schema
• Slowly Changing Dimensions (SCD)
• Fact Tables
• Dimension Tables
• Data Modeling
• ETL Design
• ELT Pipelines
• Incremental Loads
• CDC Concepts
• Workflow Automation
• Error Handling
• Logging
• Azure Data Platform
• Databricks on Azure
• Storage Integration
• Identity & Access Management
• Cost Optimization
• Introduction to Generative AI
• Large Language Models (LLMs)
• Foundation Models
• Prompt Engineering
• AI APIs
• OpenAI API Concepts
• Azure OpenAI Concepts
• Model Selection
• Embeddings
• Vector Databases
• Similarity Search
• Chunking Strategies
• Retrieval Pipelines
• Hybrid Search
• LangChain Fundamentals
• Chains
• Agents
• Memory
• Tool Calling
• Multi-Step Workflows
• LangGraph Overview
• MCP (Model Context Protocol) Concepts
• CI/CD
• GitHub
• Azure DevOps
• Monitoring
• Logging
• Testing
• Data Quality
• Deployment
• Security
• Governance
Students will build practical solutions including:
• Python ETL Scripts
• SQL Optimization Labs
• Spark Transformations
• PySpark Data Pipelines
• Databricks Notebook Development
• Delta Lake Implementation
• Azure Data Factory Pipelines
• Kafka Streaming Pipelines
• Data Warehouse Design
• Data Lake Implementation
• REST API Data Ingestion
• Incremental Loading
• RAG Pipeline
• AI Chatbot using Enterprise Data
• Vector Search Integration
• End-to-End Lakehouse Pipeline
• Python Coding Assignments
• SQL Challenges
• Spark Transformations
• Databricks Notebook Exercises
• Delta Lake Labs
• Kafka Streaming Exercises
• ADF Pipeline Development
• ETL Design
• Data Modeling
• Prompt Engineering Tasks
• RAG Implementation Exercises
Project 1
Retail Sales ETL Pipeline
Project 2
Customer Analytics Platform
Project 3
Real-Time Streaming with Kafka & PySpark
Project 4
Data Lakehouse on Databricks
Project 5
Healthcare Data Engineering Pipeline
Project 6
AI-Powered Enterprise Knowledge Assistant
Enterprise Data Lakehouse with Generative AI
The final project includes:
• Multi-source Data Ingestion
• Azure Data Lake Storage
• Databricks Processing
• Delta Lake Architecture
• Medallion Architecture (Bronze, Silver, Gold)
• Apache Kafka Streaming
• Azure Data Factory Orchestration
• Enterprise Data Warehouse
• Dashboard Data Layer
• RAG Implementation
• Enterprise AI Chatbot
• Vector Database Integration
• Production Deployment
• Monitoring & Logging
• Batch ETL Failures
• Streaming Pipeline Issues
• Data Quality Problems
• Schema Evolution
• Delta Merge Conflicts
• Late Arriving Data
• Slowly Changing Dimensions
• CDC Implementation
• Pipeline Performance Optimization
• Cloud Cost Optimization
• AI Integration into Data Pipelines
• Enterprise Data Governance
• Spark Job Failures
• Databricks Cluster Issues
• Memory Optimization
• Shuffle Problems
• Kafka Consumer Lag
• ADF Pipeline Errors
• Delta Table Corruption Recovery
• Permission Issues
• Performance Bottlenecks
• AI API Failures
• Vector Search Issues
Programming
• Python
• SQL
• Linux
Big Data
• Apache Spark
• PySpark
• Delta Lake
• Apache Kafka
Cloud
• Microsoft Azure
• Azure Data Factory
• Azure Data Lake Storage
• Azure Key Vault (Overview)
Data Platform
• Databricks
• Unity Catalog
• Databricks SQL
AI & GenAI
• OpenAI API Concepts
• Azure OpenAI Concepts
• LangChain
• LangGraph
• Vector Databases (FAISS, ChromaDB, Pinecone concepts)
• Ollama (Local LLM Overview)
DevOps
• Git
• GitHub
• Azure DevOps
• Docker
• CI/CD Concepts
• Lakehouse Architecture
• Medallion Design Pattern
• Data Quality Frameworks
• Secure Credential Management
• Performance Optimization
• Cost Optimization
• Incremental Processing
• Data Governance
• Naming Standards
• CI/CD for Data Pipelines
• AI Governance & Responsible AI
• Documentation Standards
• Databricks Certified Data Engineer Associate
• Databricks Certified Data Engineer Professional
• Microsoft Certified: Azure Data Engineer Associate (DP-203)
• Microsoft Certified: Azure Fundamentals (AZ-900)
• Microsoft Certified: Azure AI Fundamentals (AI-900)
• Apache Spark Certification (where available)
• Snowflake SnowPro Core (optional for broader career opportunities)
Our interview preparation includes:
• Python and SQL coding assessments.
• Spark and PySpark technical interviews.
• Databricks architecture discussions.
• Data modeling and ETL design questions.
• Cloud and Azure data engineering scenarios.
• GenAI, RAG, and LLM implementation discussions.
• Production support scenarios.
• HR interview preparation.
• Project presentations with expert feedback.
• Final enterprise-style mock interviews.
We help candidates with:
1. ATS-friendly resume creation.
2. Highlighting end-to-end Data Engineering projects.
3. Optimizing resumes with Databricks, Spark, Azure, and GenAI keywords.
4. Writing impactful project descriptions.
5. LinkedIn profile optimization.
6. GitHub portfolio guidance.
7. Professional summary creation.
8. Resume review sessions.
9. Role-specific resume customization.
10. Final interview-ready resume validation.
We provide comprehensive placement support through:
• Resume forwarding to 850+ Hiring Partners
• Dedicated placement team
• Technical interview scheduling
• Mock interviews
• HR interview coaching
• Career mentoring
• LinkedIn branding
• Job alerts
• Salary negotiation guidance
• Continuous support until placement
• Lakehouse Architecture
• Data Mesh
• Data Fabric
• Delta Live Tables
• Databricks Unity Catalog
• AI-Powered Data Engineering
• Generative AI for Data Pipelines
• Agentic AI
• Retrieval-Augmented Generation (RAG)
• AI Agents for Analytics
• Real-Time Analytics
• Data Observability
• Microsoft Fabric (Overview)
• Apache Iceberg & Open Table Formats (Overview)
Freshers
• Build a strong foundation in Data Engineering.
• Learn job-ready technologies through projects and hands-on labs.
• Become eligible for Junior Data Engineer roles.
1–3 Years of Experience
• Upskill to modern cloud and big data technologies.
• Transition from SQL/ETL/BI roles into Data Engineering.
• Gain practical exposure to Databricks and PySpark.
3–7 Years of Experience
• Advance into Senior Data Engineer or Lead Data Engineer roles.
• Learn scalable architectures, optimization, and AI integration.
7+ Years of Experience
• Prepare for Data Architect, Cloud Data Architect, AI Data Engineer, or Engineering Manager roles.
• Build expertise in enterprise data platforms, governance, and GenAI adoption.
Organizations are rapidly modernizing their analytics platforms using cloud-native lakehouses and real-time data pipelines. Databricks, Apache Spark, and PySpark have become core technologies for processing large-scale data, while Generative AI is creating new opportunities to build intelligent data products, AI-powered search, and enterprise knowledge assistants. Employers increasingly seek professionals who combine strong data engineering fundamentals with cloud, automation, and AI capabilities.
Over the next decade, Data Engineering is expected to remain one of the most in-demand technology domains. Growth in AI, real-time analytics, IoT, and cloud computing will continue driving demand for scalable data platforms. Professionals skilled in Databricks, PySpark, cloud data engineering, and Generative AI are expected to play a central role in building enterprise AI systems, modern data platforms, and intelligent business applications. This combination of Data Engineering and GenAI positions candidates for long-term, highgrowth career opportunities across industries.

Tools & Technologies

Every tool and library listed here is installed, configured and used in a hands-on lab session.

DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

Azure

Covered in DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

Databricks

Covered in DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

SQL

Covered in DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

PySpark

Covered in DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

10+
Tools & Libraries
388+
Hands-On Topics
38
Total Modules
1
Programme Sections

You don't just learn DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO. You apply it.

A combined capstone project across all 1 section — the same way you'd apply these skills on the job.

PROJECT // 01

DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO Capstone Project

DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

Capstone Project Combined

Apply everything you learn across DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO to one real-world project

Bring together every course in this programme into a single, end-to-end project — the same way you would apply these combined skills on the job.

A working project combining all course modules
Added directly to your project portfolio
Reviewed by mentors before you graduate
Stack Azure Databricks SQL PySpark Python LangChain GitHub Linux Data Warehousing Big Data

Hands-on Practice Areas

Hands-on Practice: DATA ENGINEERING WITH DATABRICKS, PYSPARK & GENERATIVE AI COMBO

All projects go directly into your portfolio & resume — reviewed by mentors before you graduate.

See Sample Project Reports

Upcoming Batches

No upcoming batches scheduled right now. Enquire to get notified.

Why Radical Technologies

Live Online Training
  • Highly practical oriented training
  • Installation support on your system
  • 24/7 Email and Phone support
  • 100% Placement Assistance
  • Global Certification Preparation
  • Trainer-Student Interactive Portal
  • Assignments and Projects by Mentors
Live Classroom Training
  • Weekend / Weekdays / Morning / Evening batches
  • 80:20 Practical and Theory ratio
  • Real-life Case Studies
  • Easy make-up for missed sessions
  • PSI | Kryterion | Redhat Test Centers
  • Lifetime Video Classroom Access (coming soon)
  • Resume Prep and Mock Interviews
Self-Paced Training
  • Learn 300+ courses at your own time
  • 50,000+ Satisfied Learners
  • Course Completion Certificate
  • Practical Labs available
  • Mentor Support available
  • Doubt Clearing Session available
  • 10% Discounted Global Certification

Like the Curriculum? Let's Get Started

Join 50,000+ students already enrolled at Radical Technologies

Enroll Now

Global Certification

Radical Technologies is the leading IT certification institute in Pune, offering globally recognized certifications across various domains. With expert trainers and comprehensive materials, we ensure students gain in-depth knowledge and hands-on experience to excel in their careers. Our certification programs are tailored to meet industry standards — from cloud technologies to data science — empowering individuals to stay ahead in the ever-evolving tech landscape.
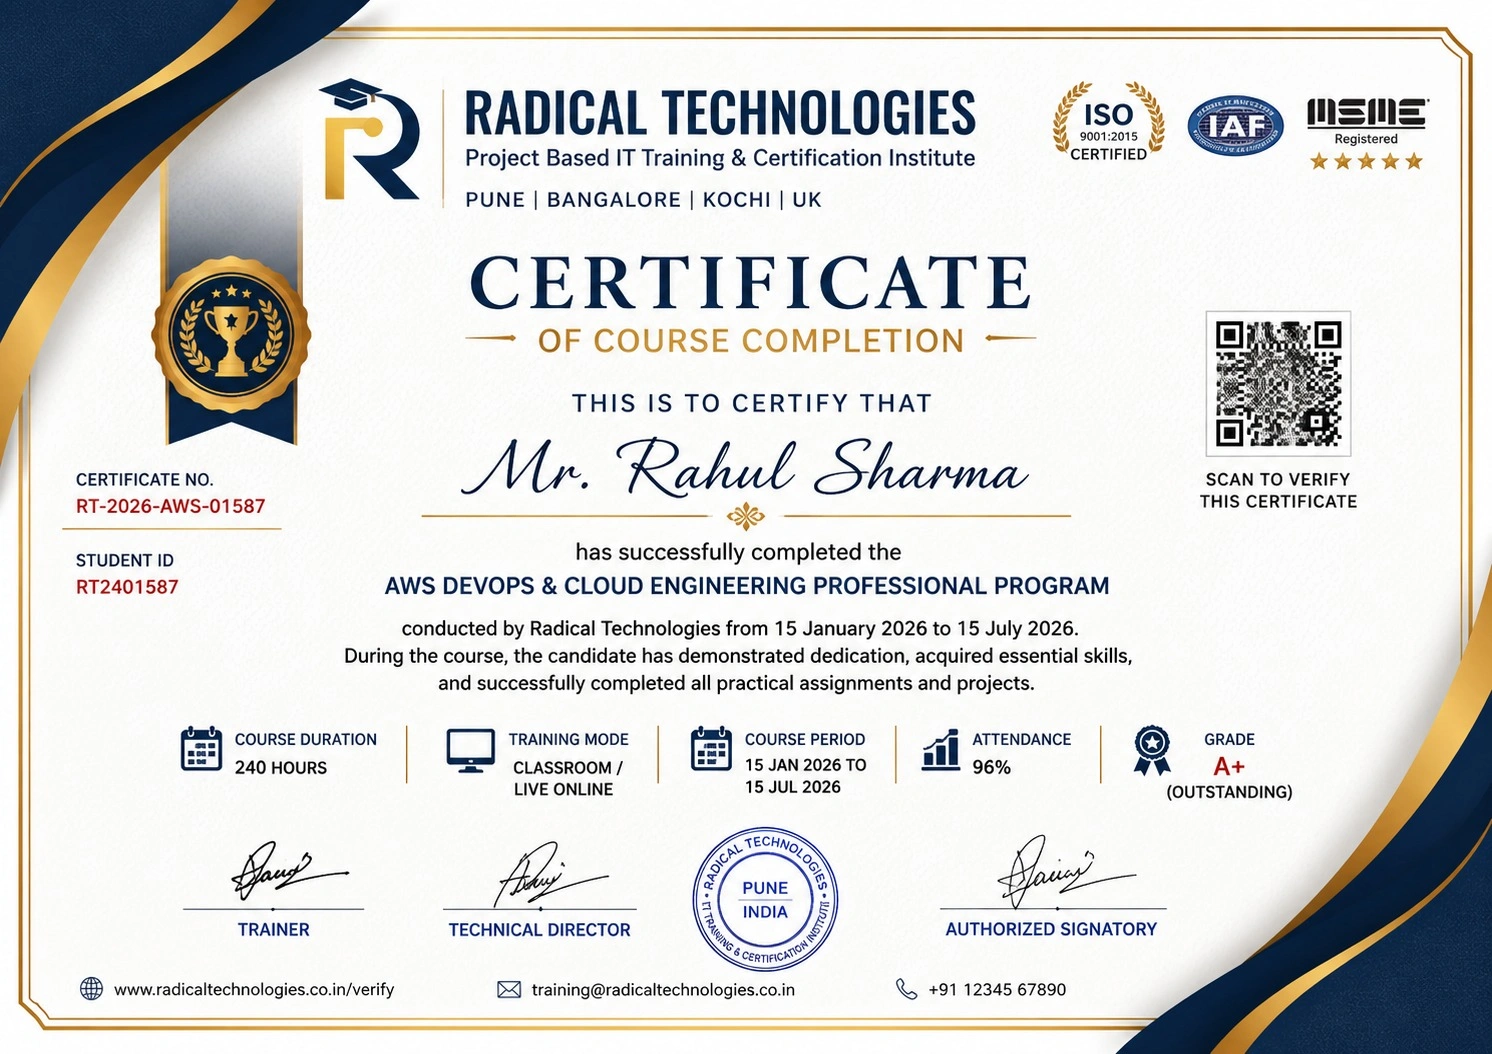
Certificate of Completion

Career Services

At Radical Technologies, we are committed to your success beyond the classroom. Our 100% Job Assistance program ensures that you are not only equipped with industry-relevant skills but also guided through the job placement process. With personalised resume building, interview preparation, and access to our extensive network of hiring partners, we help you take the next step confidently into your IT career.

Career Support

Course Completed? Need next steps?
Need Interview Supports?
Need Job Assistance?
Came from any other Institute?

Join our Brush-up Session & get support until you find a job!

Get Started

Radical Learning Eco-System

Exam Simulator

Cloud SandBox

Hands-on Cloud Lab

Developer Coding Ground

Student Reviews

4.8★
Average learner rating
50K+
Students trained
30+
Hiring companies alumni work at
100%
Placement assistance
4.8
★★★★★

Course Rating

★★★★★
85%
★★★★☆
12%
★★★☆☆
2%
★★☆☆☆
1%
★☆☆☆☆
0%

Our Alumni Work At
Accenture
Amazon
Avisys Services
Birlasoft
Capgemini
Catchpoint
Cognizant
Darwish Cybertech
DataVision
GiBots
Google
Groots Software
HCL Technologies
IBM
Info Gain
Infosys
ITCube Solutions
KPIT
L&T Infotech
Microsoft
Mphasis
mPhatek
Oracle
Quantbit Technologies
Saina Cloud
TCS
Tech Mahindra
Wipro
YASH Technologies
Zensar Technologies
Accenture
Amazon
Avisys Services
Birlasoft
Capgemini
Catchpoint
Cognizant
Darwish Cybertech
DataVision
GiBots
Google
Groots Software
HCL Technologies
IBM
Info Gain
Infosys
ITCube Solutions
KPIT
L&T Infotech
Microsoft
Mphasis
mPhatek
Oracle
Quantbit Technologies
Saina Cloud
TCS
Tech Mahindra
Wipro
YASH Technologies
Zensar Technologies

Get a Call Back from Our Career Assistance Team

Request Callback